

What do you think?
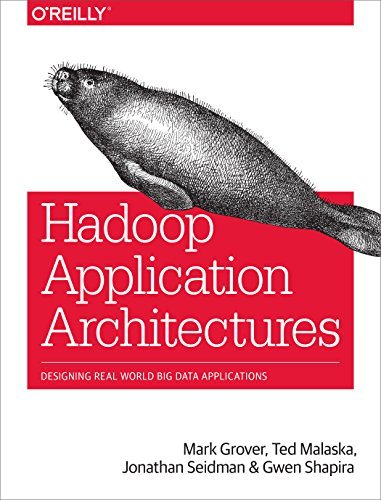
Hadoop Application Architectures: Designing Real-World Big Data Applications
Get expert guidance on architecting end-to-end data management solutions with Apache Hadoop. While many sources explain how to use various components in the Hadoop ecosystem, this practical book takes you through architectural considerations necessary to tie those components together into a complete tailored application, based on your particular use case.
To reinforce those lessons, the book’s second section provides detailed examples of architectures used in some of the most commonly found Hadoop applications. Whether you’re designing a new Hadoop application, or planning to integrate Hadoop into your existing data infrastructure, Hadoop Application Architectures will skillfully guide you through the process.
This book covers:
Factors to consider when using Hadoop to store and model data Best practices for moving data in and out of the system Data processing frameworks, including MapReduce, Spark, and Hive Common Hadoop processing patterns, such as removing duplicate records and using windowing analytics Giraph, GraphX, and other tools for large graph processing on Hadoop Using workflow orchestration and scheduling tools such as Apache Oozie Near-real-time stream processing with Apache Storm, Apache Spark Streaming, and Apache Flume Architecture examples for clickstream analysis, fraud detection, and data warehousing693 pages, Kindle Edition
First published June 30, 2015
Ratings & Reviews
Friends & Following
Create a free account to discover what your friends think of this book!
Community Reviews
Displaying 1 - 13 of 13 reviews
January 13, 2017
This is a book for software / data engineers who've been using Hadoop and related technologies for a while in practical projects, as well as for software architects looking for high level overview of how many of Big Data technology stack components relate to each other, and justifications to use which of them in different use cases.
The book is very well and clearly organized, and proceeds very logically in terms of Hadoop storage options, how to put / ingest data into a Hadoop environment, how to decide and use processing engines for Hadoop such as MapReduce, Spark, Hive, etc., how to utilize those engines to do important and critical tasks such as record deduplication, windowing analysis, and time series modification. The exposition of these fundamental building blocks are followed by graph processing on Hadoop, where both Giraph and Spark GraphX are described and contrasted. And then the topic of orchestration of Hadoop workflows are described to an extent, mainly showing how to configure and use Oozie. Part I finishes by describing Near-Realtime processing in Hadoop, and shows how Storm, Trident and Spark Streaming can be used for satisfying different requirements.
The second part of the book is dedicated to real-world use cases such as Clickstream Analytics, Fraud Detection, and Data Warehousing. The authors provide a good and broad overview for each case, clearly showing where and how Hadoop software stack helps, together with architectural recommendations, but I think the the final use case, Data Warehouse chapter is the most interesting one because it makes use of a very popular, publicly available movie data set known as MovieLens. Thanks to this, it is very easy to follow this chapter by using the same data and apply the designs and programming steps, creating your own customizations and investigating different scenarios and technical challenges you can come up with.
As a conclusion, I can recommend this book to big data architects and software engineers who are not total novices when it comes to Hadoop. The book is of course a bit date, in the very fast moving world of big data, 2015 sounds already distant past, but thanks to the extensive industrial and practical experience of authors, the way they explain their thinking and justifications for very different scenarios shed light on current and upcoming challenges for many big data engineers.

March 22, 2020
Deep enough, wide enough, good book!
It has what I expected:
1. Generic explanations about how some big data technologies work.
2. Comparison of the technologies
3. Examples of how to use them
I really wanted to learn a little about Luigi, but regarding orchestrators, the author basically knows Oozie well, and compares it to another one which has fewer features.
I took 196 highlights from this book, so quite a lot of interesting stuff!

February 18, 2016
Must read book on big data tools and architectures. It is Hadoop-centered, but it's easy to transpose most of the main principles to other systems. I like the fact, that the book is clearly targeting intermediate to advanced-level developers and assumes that you are fluent enough with SQL, Java and Scala. Too many books try to cater to novices and includes introductory chapters on programming languages or installation instructions on used tools.
My only negative comment is that both pace and level of details are a bit uneven and sometimes it glances over really interesting topics and sometimes dives into a fine details of relatively mundane ones. Of course, that's highly subjective.
My only negative comment is that both pace and level of details are a bit uneven and sometimes it glances over really interesting topics and sometimes dives into a fine details of relatively mundane ones. Of course, that's highly subjective.
May 27, 2019
Very good book on the Hadoop ecosystem from an architectural perspective. Goes well as a parallel reading to the DDIA (Designing Data-Intensive Applications) book, as a deeper dive into distributed big data processing land. I liked the first chapters which laid out the land for making architectural decisions. Most of the book is dedicated to why technology X exists, how does it solve a problem and how is it different from its alternatives. The second part glues things together by exploring different case studies and what's the best way to use the various technologies to solve a specific set of problems.
January 12, 2016
Very decent book, gives a good overview about how to use Hadoop overall, like data ingestion, storage, processing, etc. I highly recommend for everyone who are familiar with Hadoop ecosystem and want to gain better understanding in it.

May 8, 2022
Too many chapters are dedicate to brief introduction of different tools, like 2/3 of the book.
The second part (3 chapters), describing architecture for different scenarios, like EDW on Hadoop. This part was quite good - they should have done more of it.
The second part (3 chapters), describing architecture for different scenarios, like EDW on Hadoop. This part was quite good - they should have done more of it.
September 27, 2019
Good introduction to Hadoop newbies. Recommended read for programmers and architects who seek for an overview of the ecosystem.

May 11, 2021
Some chapters are still holding their value. I especially recommend the chapter 10 for a practical example on Hadoop data warehousing.

September 15, 2016
It's good, explains some of the choices, but is also very high-level.
Read
September 23, 2015Location: GG7 IRC
Accession No: DL027543
Location: ND6 IRC
Accession No: DL027544
Accession No: DL027543
Location: ND6 IRC
Accession No: DL027544

May 20, 2016
One of the better books on the topic. Sadly a bit short on case studies for unstructured data sources, which is hadoops selling point.
October 6, 2016
Book is very good. I have gained solid basics of hadoop ecosystem. It is well-written, well-prepared and authors are very knowledgeable. I highly recommend it.
Read
September 23, 2015Location: GG5 IRC
Accession No: DL027563
Accession No: DL027563
Displaying 1 - 13 of 13 reviews